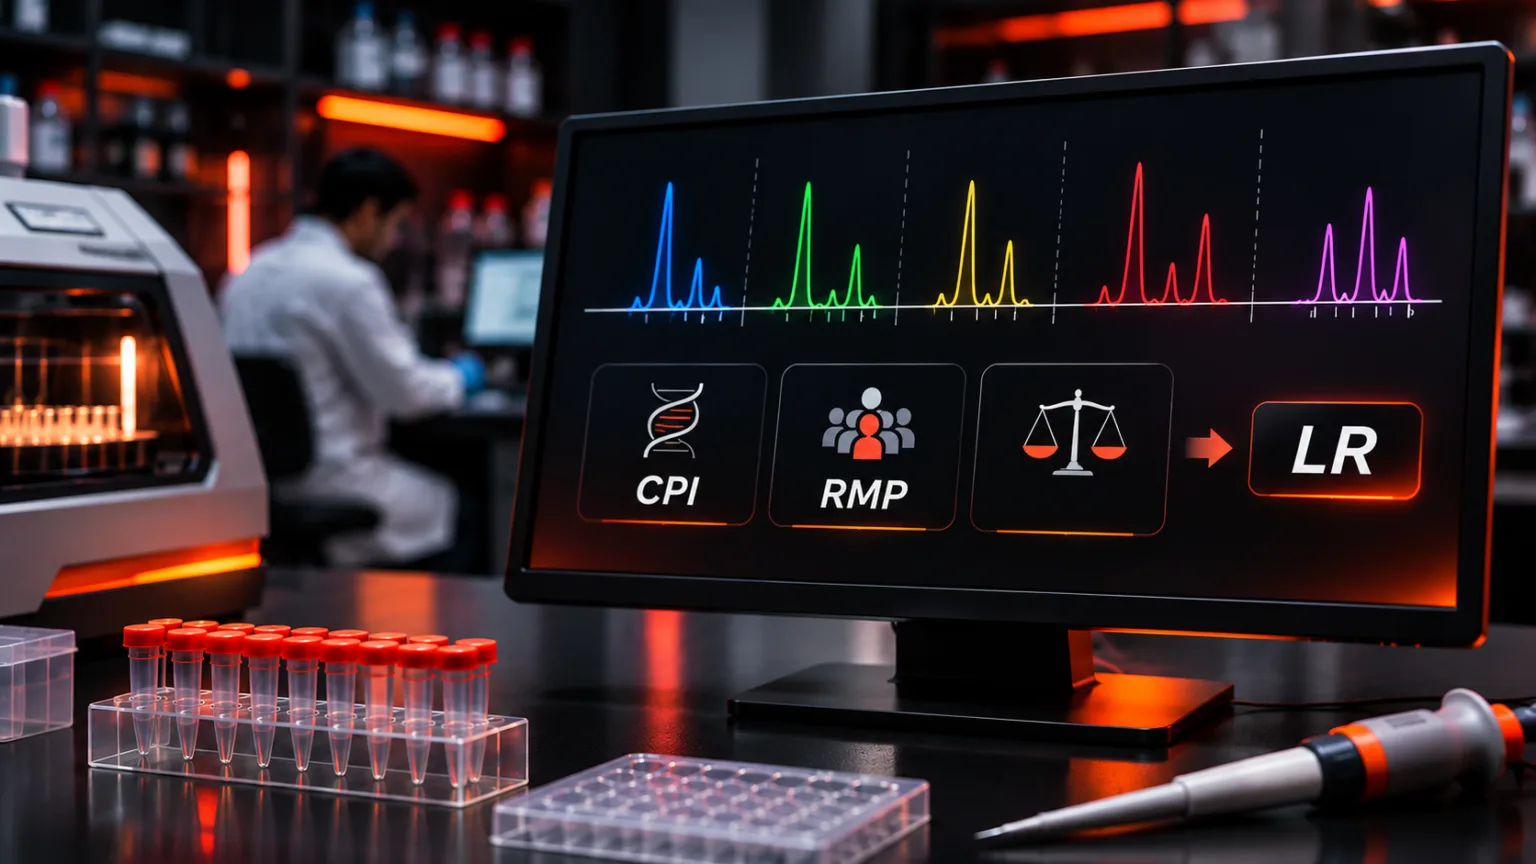
Forensic DNA DNA, or Deoxyribonucleic Acid, is the genetic material found in cells, composed of a double helix structure. It serves as the genetic blueprint for all living organisms. Read Full Definition mixture statistics quantify the evidential value of genetic findings, but the statistic must match the kind of result being evaluated. A random match probability (RMP) describes the frequencyFrequency is a fundamental concept in physics and wave theory. It refers to the number of times a specific point on a wave, such as a crest or trough, passes a fixed reference point in Read Full Definition of an interpretable genotype. The combined probability of inclusion (CPI, also termed random man not excluded or RMNE) describes what proportion of a reference population would not be excluded from a qualifying mixture. A likelihood ratio (LR) compares how probable the observed data
 Information in analog or digital form that can be transmitted or processed. Read Full Definition are under two specified alternative propositions. These methods answer different questions and cannot be treated as interchangeable measures of a match.
- RMP, CPI and LR: what question does each statistic answer?
- Figure 1: choosing an appropriate statistical question
- Random match probability: the frequency of a resolved genotype
- When is a modified RMP appropriate for a mixture?
- Combined probability of inclusion: CPI or RMNE
- Why CPI may be inappropriate for low-template mixtures
- Likelihood ratios: comparing two competing propositions
- Are 1/RMP, 1/CPI and an LR ever equal?
- From binary calculations to probabilistic genotyping
- Allelic dropout, stutter and ambiguous contributor number
- Population frequency data, Hardy–Weinberg equilibrium and θ
- Conditioning on assumed contributors
- Source-level evidence is not activity-level proof
- Validation, reproducibility and statistical sensitivity
- Reporting LR values under the 2025 SWGDAM guidance
- Analyst checklist: is this statistical result defensible?
- Common statistical interpretation errors
- Frequently asked questions
- Scientific references and technical guidance
- Related Simply Forensic Articles
- Likelihood Ratios: Statistical Strength of Forensic Evidence
- Forensic DNA Mixture Interpretation: Single-Source, Major–Minor and Unresolved Mixtures
- Number of Contributors in Forensic DNA Mixtures
- Allelic Dropout, Peak-Height Balance and Low-Template DNA
- Analytical and Stochastic Thresholds in Forensic DNA
- STR Artefacts: Stutter, Pull-Up and Troubleshooting
This technical study guide explains RMP, CPI/CPE and mixture likelihood ratios through fully calculated, synthetic examples, followed by the impact of dropout, allele sharing, population genetics, assumed contributors, relatedness and probabilistic genotyping. It draws primarily on NIST’s 2024 scientific foundation review, SWGDAM guidance, the UK Forensic Science Regulator’s DNA mixture interpretation guidance and ISFG DNA Commission recommendations. The examples are educational; every allele frequency, genotype and numerical result is hypothetical rather than an estimate from a real population database or case.
KEY LEARNING POINTS
- RMP applies to an adequately resolved single-source genotype or a reliably deduced component; it is not a plug-in formula for an unresolved mixture.
- CPI considers the set of qualifying mixture alleles
 Alleles are different forms of a gene resulting from mutations or variations in the DNA sequence or gene expression. They can be dominant (expressed with one copy) or recessive (expressed only with two copies). Read Full Definition and depends critically on the absence of relevant allelic dropout at the loci used.
- An LR evaluates observed data under two explicit competing propositions; a positive association is not automatically evidenceEvidence is any form of proof, such as objects, materials, or scientific findings, presented to establish or disprove a fact in a legal proceeding. It is used to reconstruct events and link or exclude individuals Read Full Definition of a person’s activity or guilt.
- Population databases, genotype models, assumed contributors, relatedness and the number of contributors can materially change the statistical assessment.
- Do not compare or multiply RMP, CPI and LR estimates as if they were measurements of the same quantity.

RMP, CPI and LR: what question does each statistic answer?
| Statistic | Primary question | Typical application | What it does not tell us |
|---|---|---|---|
| Random match probability (RMP) | How frequent is a specified genotype under a population model? | Single-source profile or sufficiently deduced component | Probability of guilt or an unresolved mixture’s genotype frequency |
| Combined probability of inclusion (CPI / RMNE) | What fraction of unrelated individuals would not be excluded by the qualified mixture allele sets? | Suitable unresolved mixtures under strict non-dropout assumptions | A contributor-specific LR or probability that a person donated DNA |
| Combined probability of exclusion (CPE) | What fraction would be excluded under the same CPI framework? | Complement of CPI: 1 − CPI | A different likelihood ratio or proof of exclusion for every low-template contributor |
| Likelihood ratio (LR) | How much more probable are the observations under one proposition than another? | Resolved or unresolved results, with appropriately validated models | Probability that either proposition is true, or probability of guilt |
The distinction is emphasized in NIST IR 8351. A single set of alleles can yield different types of statistics depending on whether it is regarded as a deduced genotype, an unresolved mixture or quantitative evidence evaluated under competing propositions. That is why the statistical strategy must be chosen through a documented, validated interpretation process.
Figure 1: choosing an appropriate statistical question
STATISTICAL INTERPRETATION · CONCEPTUAL DECISION MAP
Resolved source profile
One genotype is reliably inferred, within validated criteria.
RMP / justified modified RMP
Unresolved but qualified mixture
Relevant alleles accepted; no reasonable dropout risk for included CPI loci.
CPI/CPE may be eligible
Complex or stochastic mixture
Dropout, sharing, stutter or contributor uncertainty needs explicit treatment.
Validated LR evaluation may be appropriate
Random match probability: the frequency of a resolved genotype
A random match probability estimates the probability that a randomly selected unrelated person from a defined population would have the particular genotype being considered, conditional on the frequency and population model. Under Hardy–Weinberg equilibrium for a simple autosomal locus A locus is the precise position of a gene on a chromosome. Different alleles of the same gene occupy the same locus. Read Full Definition, the genotype frequency is p² for a homozygote A/A and 2pq for a heterozygote A/B, where p and q are the corresponding allele frequencies. For suitable statistically unlinked loci, multilocus profile frequencies can be combined using the product rule, with appropriate population-genetic adjustments.
These are genotype frequencies, not probabilities that a specific defendant is innocent or guilty. A person may have a common two-locus genotype yet be the true donor; another person may share a much rarer full STR profile by coincidence. The RMP measures the rarity of the genotype under the chosen model, not whether the evidentiary material came from the person or why it was deposited.
Worked example 1: single-locus and multilocus RMP
Assume that at hypothetical locus 1, allele 10 has population frequency 0.30 and allele 12 has frequency 0.50. A resolved heterozygous genotype 10,12 has:
P(10,12) = 2 × 0.30 × 0.50 = 0.30 (30%).
At a statistically unlinked hypothetical locus 2, allele 14 has frequency 0.20 and allele 16 has frequency 0.40, giving P(14,16) = 2 × 0.20 × 0.40 = 0.16.
| Locus | Inferred genotype | Hypothetical frequencies | Genotype probability |
|---|---|---|---|
| Locus 1 | 10,12 | p(10)=0.30; p(12)=0.50 | 2 × 0.30 × 0.50 = 0.30 |
| Locus 2 | 14,16 | p(14)=0.20; p(16)=0.40 | 2 × 0.20 × 0.40 = 0.16 |
| Combined | Two-locus profile | Assumed locus independence | 0.30 × 0.16 = 0.048 |
The illustrative two-locus RMP is 0.048, or 4.8%—approximately 1 in 20.8 unrelated individuals. Two loci are intentionally uninformative relative to modern multi-STR systems. The example demonstrates the multiplication, not casework-level discrimination. Actual calculations may incorporate θ correction, database sampling uncertainty and other laboratory rules; those adjustments are omitted here.
When is a modified RMP appropriate for a mixture?
Where a mixture has a clearly deduced major component, or some loci permit a specifically qualified source-profile inference, laboratories may use a modified RMP procedure appropriate to the inferred partial or complete profile. It must not be confused with blindly applying the single-source product rule to every allele seen in a mixture. A partially inferred genotype with an unresolved partner allele requires an authorized treatment of that uncertainty; methods such as a 2p rule have been discussed for particular partial single-source contexts, not as a universal adjustment to CPI.
The fundamental safeguard is the reliability of the deconvolution. A major component inferred by peak-height inspection alone may be compromised by allele sharing or a low-level contributor. If a specific genotype cannot be reliably inferred, a conventional full-profile RMP should not be presented as though the genotype were directly observed. For methods and limitations, see our guide to distinguishable and unresolved mixtures.
Combined probability of inclusion: CPI or RMNE
Combined probability of inclusion (CPI) expresses the probability that an unrelated random individual would not be excluded as a possible contributor under the mixture’s selected and qualified allele sets. Unlike RMP, it does not seek to determine precisely which pair of alleles came from each contributor. At a suitable locus, the probability of inclusion (PI) is obtained by summing the population frequencies of the accepted alleles and squaring that sum under a simple Hardy–Weinberg framework:
PI(locus) = [Σ p(accepted allele)]²
CPI = PI₁ × PI₂ × … × PIₙ
CPE = 1 − CPI
The squared frequency sum represents the probability that both alleles of an unrelated person’s genotype would be drawn from that accepted set. It does not mean that the person carries every observed allele or that their full genotype was reconstructed. The calculation assumes suitable population data, independent loci and—critically—an interpretation framework under which relevant alleles are not missing from the loci selected for CPI.
Worked example 2: two-locus CPI and CPE
At hypothetical locus A, the accepted mixture alleles have frequencies 0.30, 0.25 and 0.15, totalling 0.70. Other alleles not in the accepted set account for frequency 0.30. At hypothetical locus B, the accepted alleles have frequencies 0.10 and 0.20, totalling 0.30, while other alleles account for 0.70. Assume no relevant dropout and that the loci qualify under the laboratory’s validated CPI protocol.
| Locus | Accepted allele frequencies | Calculation | PI |
|---|---|---|---|
| A | 0.30 + 0.25 + 0.15 | (0.70)² | 0.49 |
| B | 0.10 + 0.20 | (0.30)² | 0.09 |
| Combined | Two qualifying loci | 0.49 × 0.09 | CPI = 0.0441 |
Thus CPI is 4.41%: approximately one in 22.7 randomly selected unrelated individuals would have genotypes that are not excluded by those accepted allele sets. Its complement is CPE = 1 − 0.0441 = 0.9559, or 95.59% excluded under the same model. An inverse CPI (1/0.0441 ≈ 22.7) is not automatically a likelihood ratio, and it does not prove that a particular person contributed the DNA.
Published protocols by Bieber, Buckleton, Budowle, Butler and Coble (2016) emphasize making suitable locus and allele-classification decisions before performing CPI. They specifically caution against including loci with a reasonable probability of allele dropout. A stutter-position signal that might be a genuine allele can also affect the accepted set; interpretation must be driven by a validated protocol rather than by the identity of the person being compared.
Why CPI may be inappropriate for low-template mixtures
Consider a genuine contributor with genotype 10,15 at one locus, while only allele 10 is detected because allele 15 drops out. A conventional no-dropout CPI comparison could incorrectly find the person’s 15 allele absent from the accepted set and exclude a true contributor. The calculation’s premise—that the alleles of possible contributors are adequately represented—is not met. A large peak above a stochastic threshold does not guarantee that an allele from a weak, overlapping contributor has been recovered. See our low-template and dropout worked examples.
CPI also discards useful quantitative information. It does not formally account for which contributor generated a tall peak, which generated a small peak, or how strongly particular genotype combinations explain the observations. Perlin (2015) criticized CPI’s limited contributor-specific information, while Bieber and colleagues (2016) published a detailed protocol defending its conditional usefulness when strict suitability rules are followed. These positions should not be simplified into a claim that CPI is always invalid or always conservative.
In particular, one should not multiply an RMP calculated at some loci by a CPI calculated at other loci as though the values were components of one validated probability model. The mathematical quantities and conditioning can differ; any combined method needs a separately established statistical justification.
Likelihood ratios: comparing two competing propositions
A likelihood ratio (LR) evaluates the relative probability of the same observed genetic data under two distinct propositions. A common source-level pair for a two-person mixture is H₁: the person of interest (POI) and one unknown unrelated person contributed; versus H₂: two unknown unrelated people contributed instead. The numerator and denominator refer to the probability of the observations, not to the probability that the propositions are true.
LR = P(observed DNA results | H₁) ÷ P(observed DNA results | H₂)
For this orientation, an LR above 1 favours H₁ relative to H₂; below 1 favours H₂; and exactly 1 is uninformative. The LR does not include the prior odds of the propositions. It is also not a probability of guilt or a direct statement about how or when the DNA reached the item. This distinction is central to ISFG’s 2018 proposition guidance.
Worked example 3: a complete exact single-locus mixture LR
To show the mathematics without a black-box calculation, consider a synthetic two-person mixture at one diploidDiploid is the quality of a cell or organism having two sets of chromosomes, one from each parent. Sexually reproducing organisms are diploid. In humans, only their egg and sperm cells are haploid. Read Full Definition autosomal locus. The only observed allele states are A, B and C, and all genuine alleles are assumed detected: no dropout, drop-in, stutter contribution, contaminationContamination - The unwanted transfer of material from another source to a piece of physical evidence. The inadvertent touching of a weapon, thereby adding fingerprints to it is an example of evidence contamination. Read Full Definition, allelic imbalance or peak-height information is included in this toy model. Each contributor has two alleles. Genotypes follow Hardy–Weinberg proportions and unrelated contributors are sampled independently, with no θ adjustment.
| Allele category | A | B | C | All other alleles |
|---|---|---|---|---|
| Hypothetical frequency | 0.30 | 0.25 | 0.20 | 0.25 |
Under H₁, the POI has known genotype A/B and is one contributor; the other contributor is unknown. To produce the exact observed set {A, B, C}, the unknown person’s genotype must be C/C, A/C or B/C. The probabilities are:
P(E | H₁) = (0.20)² + 2(0.30)(0.20) + 2(0.25)(0.20)
= 0.04 + 0.12 + 0.10 = 0.26.
Under H₂, two unrelated unknown individuals are contributors. Across their four allele draws, all observed categories A, B and C must occur at least once, and no allele from the remaining 0.25 probability mass may occur. By inclusion–exclusion:
P(E | H₂) = (0.75)⁴ − (0.45)⁴ − (0.50)⁴ − (0.55)⁴ + (0.30)⁴ + (0.25)⁴ + (0.20)⁴ = 0.135.
Therefore LR = 0.26 / 0.135 = 1.9259 (approximately 1.93). In this narrowly defined hypothetical model, the observed allele set is about 1.93 times as probable under H₁ as under H₂. This is only slight support for H₁ over H₂, not proof of a match or a conclusion that the POI supplied the sample. A more realistic peak-height model, additional loci, related contributors, dropout or population correction would change the calculation.
FIGURE 2 · EXACT HYPOTHETICAL LIKELIHOODS
0.260
0.135
The precise"Precise" refers to the degree of closeness or consistency between multiple measurements or values taken under the same conditions. It indicates how well these measurements agree with each other, regardless of whether they are accurate Read Full Definition calculation matters. Incomplete teaching demonstrations sometimes insert a guessed denominator, giving a superficially impressive LR with no derivation. The numerical result is only defensible when both likelihoods follow from the same observations and explicitly defined models.
Are 1/RMP, 1/CPI and an LR ever equal?
In a simple high-quality single-source situation with idealized propositions, no uncertainty and a known matching POI, an LR may take the form of the inverse of the profile probability. That does not generalize automatically to complex mixtures. 1/CPI is an inverse inclusion probability, not an LR merely because both might be reported as “one in X.” CPI asks whether random genotypes fall within accepted allele sets; an LR weighs how well the observations follow from two specified scenarios, potentially using genotype frequencies, peak heights, dropout models and the number of contributors.
In practice, a laboratory should not select whichever statistic sounds largest. The scientific goal is not to maximize the numerical weight of association but to use a validated procedure that answers the relevant case question with the data that actually exist.
From binary calculations to probabilistic genotyping
Binary models consider the presence or absence of accepted alleles under specified assumptions. Some can formulate an LR while others yield profile probabilities or CPI. Binary calculations are particularly vulnerable if they presume complete detection when the sample is low template. Semi-continuous probabilistic genotyping (PG) accommodates uncertainty in allele detection, dropout and sometimes drop-in, without modelling every observed peak height. Fully continuous PG typically uses quantitative peak heights alongside parameters for mixture proportions, stochastic effects, stutter and other features.
| Approach | Observed data emphasized | Stochastic effects | Main caution |
|---|---|---|---|
| Binary comparison / LR | Allele presence/absence and defined genotype combinations | Depends on the specific model and suitability rules | Unmodelled dropout can invalidate assumptions |
| Semi-continuous PG | Allele calls and probability of detecting alleles | Explicit dropout and potentially drop-in modelling | Cannot generally exploit all peak-height differences |
| Fully continuous PG | Allele calls and relative quantitative signal | Models peak-height variation, mixture ratios and artefacts | Parameter estimation, convergence, diagnostics and validationValidation, often referred to as method validation, is a crucial process in the laboratory when introducing a new machine, technology, or analytical technique. It involves a series of systematic steps and assessments to ensure that Read Full Definition remain essential |
Statistical software cannot independently verify the analytical correctness of a peak call or repair invalid data. The reliability of input files, contributor number assumptions, software validation and suitable quantitative models remains central to evidential evaluation. See SWGDAM’s 2025 PG guidance and the NIST scientific foundation review for detailed discussion.
Allelic dropout, stutter and ambiguous contributor number
DNA mixtures become statistically difficult when the observed peaks do not uniquely determine the underlying genotypes. Allele sharing can make a high peak represent more than one contributor. Stutter can create a signal at the same allele position as a genuine minor-contributor allele. Dropout means a true contributor allele might not be among the accepted peaks. These uncertainties affect whether a binary statistic is suitable and how much weight a probabilistic model gives a set of genotype possibilities.
Contributor number is also a model choice. For example, a three-person mixture analysed with a two-person assumption can produce misleading exclusions or unusual fit patterns, while adding unjustified contributors may alter the balance of evidence. A valid interpretation should consider the evidence independently from the POI where applicable and document why the chosen NOC is within the laboratory’s validated scope. Our NOC worked examples and STR artefact guide explain these analytical precursors.
In the UK FSR guidance, uncertainty about NOC may be addressed through sensitivityIn the context of laboratory equipment or analytical techniques, the term "sensitive" describes the capability of a machine or method to detect even very small amounts or concentrations of a substance. Sensitivity is a quantitative Read Full Definition analyses or statistical methods that average likelihoods across plausible NOC values with justified weighting. This is not the same as simply computing several LRs, selecting the most favourable and calling it conservative.
Population frequency data, Hardy–Weinberg equilibrium and θ
Allele frequencies must come from relevant, quality-controlled population databases and suitable population models. Straightforward genotype calculations assume Hardy–Weinberg proportions, and products across loci depend on appropriate independence assumptions. Population substructure can make genetically related or geographically clustered individuals more likely to share alleles than a simple population-wide model suggests. Forensic calculations may incorporate a coancestry correction commonly symbolized θ (theta) or FST, following validated laboratory policy and population genetics guidance.
When an allele is absent or rare in the reference database, sample-size uncertainty and minimum allele-frequency procedures may be relevant. No one minimum frequency rule—such as 1/(2N) or 5/(2N)—should be presented as universal without establishing the method and reference population. Similarly, a theta value that is appropriate for one population or jurisdiction cannot automatically be imported into another laboratory’s calculation.
Related individuals require more than a routine unrelated-individual population correction. A proposition that the true contributor is the POI’s sibling is genetically different from a proposition involving a random unrelated donor, and may produce a substantially different LR. NIST’s scientific review gives examples in which changing population correction or substituting a relative into the alternative proposition meaningfully changes evidential weight. If related contributors are a realistic alternative, the statistical evaluation must address that scenario explicitly.
Conditioning on assumed contributors
Sometimes the presence of a person’s DNA is independently established or reasonably undisputed, such as a consensual intimate sample involving the individual from whom it was collected. The analystA designated person who examines and analyzes seized drugs or related materials, or directs such examinations to be done; independently has access to unsealed evidence in order to remove samples from the evidentiary material for Read Full Definition may then evaluate an unknown component conditional on the assumed person’s genotype. That choice changes the propositions and the genotype combinations evaluated. It must be justified by case circumstances, documented and supported by validated procedures.
Conditioning is not simply subtracting all matching peaks. If two contributors share allele 12, it is one observed peak position, not two separable signals that can be removed one by one. Where the presence of an assumed contributor is disputed, conditioning without justification can biasThe difference between the expectation of the test results and an accepted reference value. Read Full Definition the result and presuppose the very issue that needs evaluation. Propositions should be framed as much as possible without relying on whether the POI’s genotype happens to match the evidence, as emphasized by ISFG guidance.
Source-level evidence is not activity-level proof
A source- or sub-source-level LR addresses the question of whose DNA could explain the observed profile. It does not independently establish whether DNA was deposited during an assault, transferred indirectly, persisted from earlier contact or arose by contamination. Those are activity-level possibilities, which require different evidence, information about transfer and persistence and appropriately formulated activity propositions.
An LR of 10,000 under a source-level comparison does not mean that the alleged Alleged is a term used in legal contexts to describe an accusation or claim that has been made against an individual but has not yet been proven or confirmed. Read Full Definition criminal activity is 10,000 times more likely. Nor does an RMP of one in a million mean there is a one-in-a-million chance the POI is innocent. Such transpositions confuse the probability of observed evidence given a proposition with the probability of the proposition given observed evidence. Our hierarchy-of-propositions guide examines this issue in greater detail.
Validation, reproducibility and statistical sensitivity
Before using a statistical method in casework, laboratories should validate the relevant STR assays and interpretation system over realistic ranges of contributors, ratios, DNA inputs, degradation, artefact levels and stochastic behaviour. For PG, validation includes known-contributor and known-non-contributor samples, checks of model performance, sensitivity and specificityIn the context of laboratory equipment or analytical techniques, the term "specific" describes the capability of a machine or method to accurately and selectively detect particular molecules or substances while minimizing interference from others. Specificity Read Full Definition, fit or convergence diagnostics where applicable, and review of behaviour near interpretive boundaries. Procedures should describe how different seeds, population datasets and plausible assumptions are handled.
The 2025 SWGDAM probabilistic-genotyping document and 2025 LR reporting guidelines require transparent treatment of relevant results and reporting conventions in their specified guidance. In the United States, the FBI Quality Assurance Standards for Forensic DNA Testing Laboratories (effective July 1, 2025) set applicable requirements for laboratories within scope. SWGDAM guidelines and UK FSR documents have different legal and professional status depending on jurisdiction: the presence of a recommendation does not make it a universally binding rule.
AccuracyIn scientific and measurement contexts, "accuracy" refers to the degree of proximity or closeness between a measured value and the true or actual value of the measured quantity. Accuracy indicates how well a measurement reflects Read Full Definition matters more than obtaining an impressive number. The review should ask: Were genotype frequencies correctly calculated? Are all included CPI loci qualified for a no-dropout treatment? Are the LR numerator and denominator based on the same data? Were the propositions and conditioning assumptions appropriate? Has stochastic uncertainty been represented? Are software diagnostics and non-contributor performance within validated limits? Are any changes from the initial analysis recorded?
Reporting LR values under the 2025 SWGDAM guidance
SWGDAM’s Guidelines for Reporting Likelihood Ratios (approved April 7, 2025; corrected April 30, 2025) recommend reporting the numerical LR rather than using an unsupported verbal label alone. LRs above 1 and below 1 should be presented with their appropriate direction of support. The document provides an optional standardized verbal scale, accompanied by the numerical result and the complete scale when used:
| LR supporting the favoured proposition | SWGDAM verbal category |
|---|---|
| 1 | Uninformative |
| 2 to less than 100 | Limited support |
| 100 to less than 10,000 | Moderate support |
| 10,000 to less than 1,000,000 | Strong support |
| At least 1,000,000 | Very strong support |
The scale gives no separate verbal interval for values strictly between 1 and 2. Consequently, the synthetic LR of approximately 1.93 above should be reported numerically and explained plainly, not automatically assigned the “limited support” label from a range that begins at 2. Laboratories must follow their approved reporting procedures. SWGDAM also cautions that an LR near 1 is not automatically an “inconclusive zone” and that results favouring the alternative proposition can have genuine evidential relevance.
Illustrative reporting statements
RMP example: “Under the specified population model, the probability of the inferred genotype being observed in a randomly selected unrelated individual is approximately 0.048.” This refers only to the deliberately simple two-locus demonstration above.
CPI example: “For the qualifying mixture loci, the combined probability of inclusion is 0.0441 under the stated no-dropout and population assumptions.” It is essential to state which loci qualified and whether the person of interest is consistent with the accepted allele sets.
LR example: “Under the illustrative one-locus model, the observed allele set is approximately 1.93 times more probable if the person of interest and one unrelated unknown contributed than if two unrelated unknown individuals contributed.” The calculation must identify its propositions and modelling assumptions. These are teaching formulations, not a substitute for laboratory-approved reporting text.
Analyst checklist: is this statistical result defensible?
- Verify data quality: confirm that the STR profile, controls, allelic calls and artefact classifications are suitable for the method chosen.
- Define the question: decide whether the result is a deduced genotype frequency, a non-exclusion calculation or an evidential LR. Do not convert one into another by implication.
- Check the assumptions: document dropout suitability, accepted allele sets, putative NOC, conditioning contributors and whether peak heights are modelled.
- Inspect population inputs: verify the reference database, allele frequencies, rare-allele procedures, HWE and linkage assumptions, θ correction and relevant relatedness alternatives.
- Recalculate simple examples independently: check heterozygote factors of 2, sums of allele frequencies, multiplication of loci and the direction of numerator and denominator.
- Inspect model performance: where PG is used, review validated scope, software diagnostics, replicate decisions, sensitivity and plausible alternative propositions.
- Report the conditional statement: present the statistic with its assumptions and proper interpretation, avoiding activity-level or posterior-probability claims from source-level evidence.
FIGURE 3 · DO NOT TRANSPOSE THE CONDITIONAL
What an LR compares
P(E | H₁) versus P(E | H₂)
How probable are the observed DNA results under each stated proposition?
What an LR does not supply
P(H₁ | E)
The probability a proposition is true after seeing the evidence would also require prior odds.
Common statistical interpretation errors
| Misinterpretation | Why it is wrong | Correct principle |
|---|---|---|
| “A 1-in-1,000,000 RMP means one chance in a million the POI is innocent.” | It transposes the conditional probability | RMP concerns profile rarity, not posterior guilt probability |
| “CPI⁻¹ is always a likelihood ratio.” | The statistics answer different questions | Keep inclusion probability separate from proposition-specific LR |
| “Every peak above ST makes CPI safe.” | Shared peaks may conceal dropout for a low-level donor | Qualify loci using laboratory validation and the full mixture |
| “Multiplying RMP at one locus by CPI at another is fine.” | Different conditional models may be inappropriately combined | Use a coherent, validated statistical formulation |
| “A numerical LR is the probability the POI contributed.” | LR compares data probabilities under hypotheses, not the hypotheses themselves | Report the propositions and evidential-weight ratio |
| “A large source LR proves the alleged activity.” | Source and activity propositions concern different questions | Do not transfer DNA-level weight directly to activity or guilt |
Continue within this series: The next step is to examine how probabilistic genotyping evaluates complex profiles and how forensic DNA reports communicate the resulting evidential weight.
Frequently asked questions
What is the difference between RMP and CPI?
RMP describes the frequency of a specified genotype; CPI describes the probability that a random person’s genotype would be non-excluded under the accepted allele sets of a suitable mixture. Neither is automatically a mixture LR.
Is CPI still scientifically valid?
It can be appropriate for profiles and loci that satisfy a validated CPI procedure, particularly where relevant allelic dropout is not reasonably expected. It provides less contributor-specific information than a suitable quantitative LR model and should not be used if its assumptions are violated.
Does an LR of 1000 mean a 99.9% probability the suspect contributed?
No. It means the evidence is 1,000 times as probable under one specified proposition than under another, given the chosen model. Posterior proposition probabilities would additionally depend on prior odds and cannot be inferred from the LR alone.
Can CPI be used when allelic dropout is suspected?
Ordinary no-dropout CPI should not use loci with a reasonable probability of dropout. A different validated statistical approach that represents stochastic uncertainty is needed for those data.
Why can a sibling hypothesis change the LR?
A close relative is more likely than a random unrelated person to share the POI’s genotype. Replacing an unrelated alternative contributor with a sibling changes the denominator model and potentially the resulting strength of evidence.
Can a laboratory report a likelihood ratio below 1?
Yes. For the stated orientation, an LR below 1 favours the alternative proposition; the reciprocal can help express the degree of support in that direction. Reporting must follow the laboratory’s procedures and relevant current guidance.
Is probabilistic genotyping a substitute for analyst review?
No. The analyst must confirm data quality, validated model scope, appropriate propositions and software diagnostics. PG provides a statistical assessment conditional on its input and assumptions.
Scientific references and technical guidance
View scientific references (11)
- Butler JM, Iyer H, Press R, Taylor MK, Vallone PM, Willis S. DNA Mixture Interpretation: A NIST Scientific Foundation Review. National Institute of Standards and Technology. NIST IR 8351. 2024.
- Scientific Working Group on DNA Analysis Methods (SWGDAM). Interpretation Guidelines for Autosomal STR Typing by Forensic DNA Testing Laboratories. Revised July 2021.
- SWGDAM. Guidelines for the Use of Probabilistic Genotyping with Autosomal STR Typing Results. 2025.
- SWGDAM. Guidelines for Reporting Likelihood Ratios. Approved April 7, 2025; corrected April 30, 2025.
- Forensic ScienceDiscover the fascinating field of Forensic Science, the application of scientific principles to legal matters. This post delves into its many disciplines, from DNA analysis to crime scene investigation, its importance in the justice system, Read Full Definition Regulator. DNA Mixture Interpretation (FSR-G-222). Issue 3; accessible version updated 2024.
- Gill P, Hicks T, Butler JM, et al. ISFG DNA Commission: Assessing the value of forensic biological evidence—Part I: Evaluation of DNA profiling comparisons given (sub-)source propositions. Forensic Science International: Genetics. 2018;36:189–202.
- Bieber FR, Buckleton JS, Budowle B, Butler JM, Coble MD. Evaluation of forensic DNA mixture evidence: Protocol for evaluation, interpretation, and statistical calculations using the combined probability of inclusion. BMC Genetics. 2016;17:125.
- Gill P, Gusmão L, Haned H, et al. DNA Commission of the ISFG: Recommendations on the evaluation of STR typing results that may include drop-out and/or drop-in using probabilistic methods. Forensic Science International: Genetics. 2012;6:679–688.
- Perlin MW. Inclusion probability for DNA mixtures is a subjective one-sided match statistic unrelated to identification information. Journal of Pathology Informatics. 2015;6:59.
- National Research Council. The Evaluation of Forensic DNA Evidence. National Academies Press. 1996.
- Federal Bureau of Investigation. Quality Assurance Standards for Forensic DNA Testing Laboratories. Effective July 1, 2025.